Sign in
Use your email or service name to access the operator dashboard.
Register for Beta
Create a service account. You will receive a verification email, then your request will be reviewed before you can sign in.
Verify your email
Verifying your email address…
The Open-Source Decentralized Inference Mesh
Boost inference from the mesh when you need more power — share yours when you don’t.
Designed to scale agent workloads across peers you choose — no mandatory cloud inference. Public Beta — features may change. Terms & Privacy.
Shared intelligence, on your terms
Install mtrxAI, point your tools at it, and join a private team, a public regional cluster, or a small invited group. Hardware sharing is always optional.
How it works
- Install on each machine you want in the mesh.
- Point your apps at the local OpenAI-compatible proxy.
- Inference stays local when the model is on your GPU.
- Otherwise a peer in your cluster or swarm runs it.
Features
- Built-in chat plus a drop-in proxy for agents and tools.
- Manage local LLM servers, pull models, set per-model visibility.
- Clusters and swarms, side by side.
- Schedules, thermal guards, and a kill switch for sharing.
Clusters
- Private invite-only teams for laptops and GPU workstations.
- Public regional clusters when you want a wider mesh.
- No copying multi-gigabyte weights across machines.
- Relay available when a direct path cannot be opened.
Security
- You control who sees your node and what you share.
- End-to-end encryption on inference payloads by default.
- Transport encryption: WebRTC DTLS and libp2p Noise.
- Device attestation, peer block/report, dual-verified credits.
Join the mesh. Share on your terms.
Built to scale agents across peers without requiring a cloud. Pull the container, join a cluster or swarm, point your apps at the local proxy.
View on Docker HubDesktop builds are CLI peer binaries (v0.4.0). Public Beta — features may change. Terms & Privacy.
How It Works
mtrxAI sits between your apps and the mesh. Here is what happens in plain language.
Four steps
Install
Run mtrxAI on each machine you want in the mesh — Docker today; desktop and Android builds are coming.
Point your apps
Tell your AI tools to use the local mtrxAI endpoint. Same OpenAI-style setup you already know.
Run here if you can
If the model is on your machine, inference stays local — fastest path, nothing leaves your computer.
Ask a peer if you need to
If the model is not local, mtrxAI finds a computer in your cluster or swarm that has it, and that peer runs the request.
Teams and small groups
Two ways to connect — you can use both at once.
Teams (clusters)
Invite-only or regional groups with discovery, ranking, and credit tracking so everyone can see who used what.
Small groups (swarms)
High-trust circles that join with a shared token. No central ledger — just peers helping each other.
Want the protocol detail? See Architecture.
Features
Everything you need to run models locally, join private or public meshes, and keep control of your hardware.
Use AI on your terms
Built-in chat
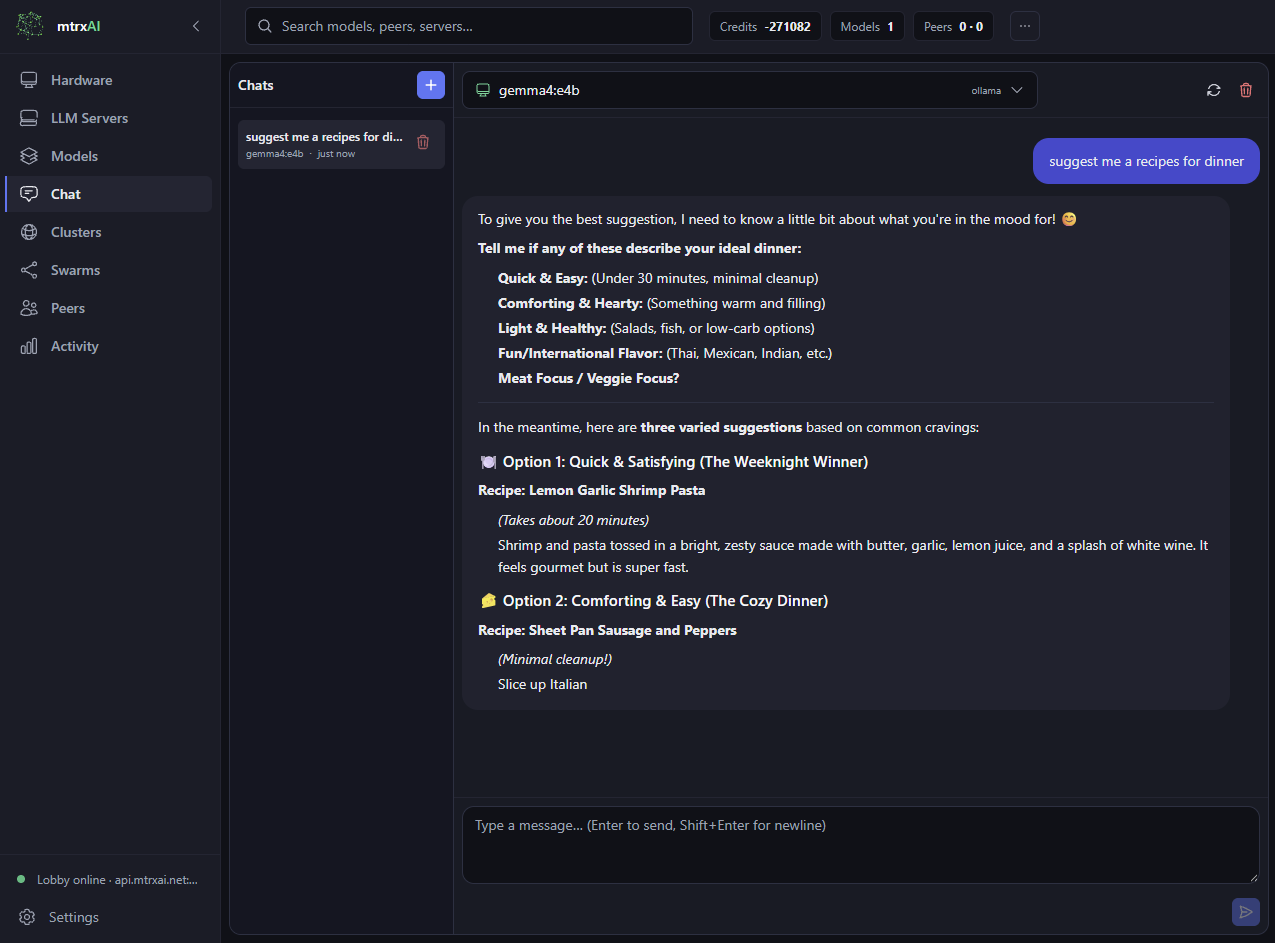
Talk to local and mesh models from the dashboard, with saved sessions you can reopen later.
OpenAI-compatible proxy
Point Cursor, agents, and other tools at localhost. Streaming and tool calling work as usual.
Local first
If the model is on your GPU, the workload stays there — zero network delay.
Smart peer choice
When you need remote help, mtrxAI prefers nearby machines and lighter load.
Connect the way you want
Clusters & swarms
Managed teams with credits, or token-joined small groups — run both at the same time.
Private & public teams
Invite-only private clusters, or join a public regional community when you want a wider mesh.
Peer approval
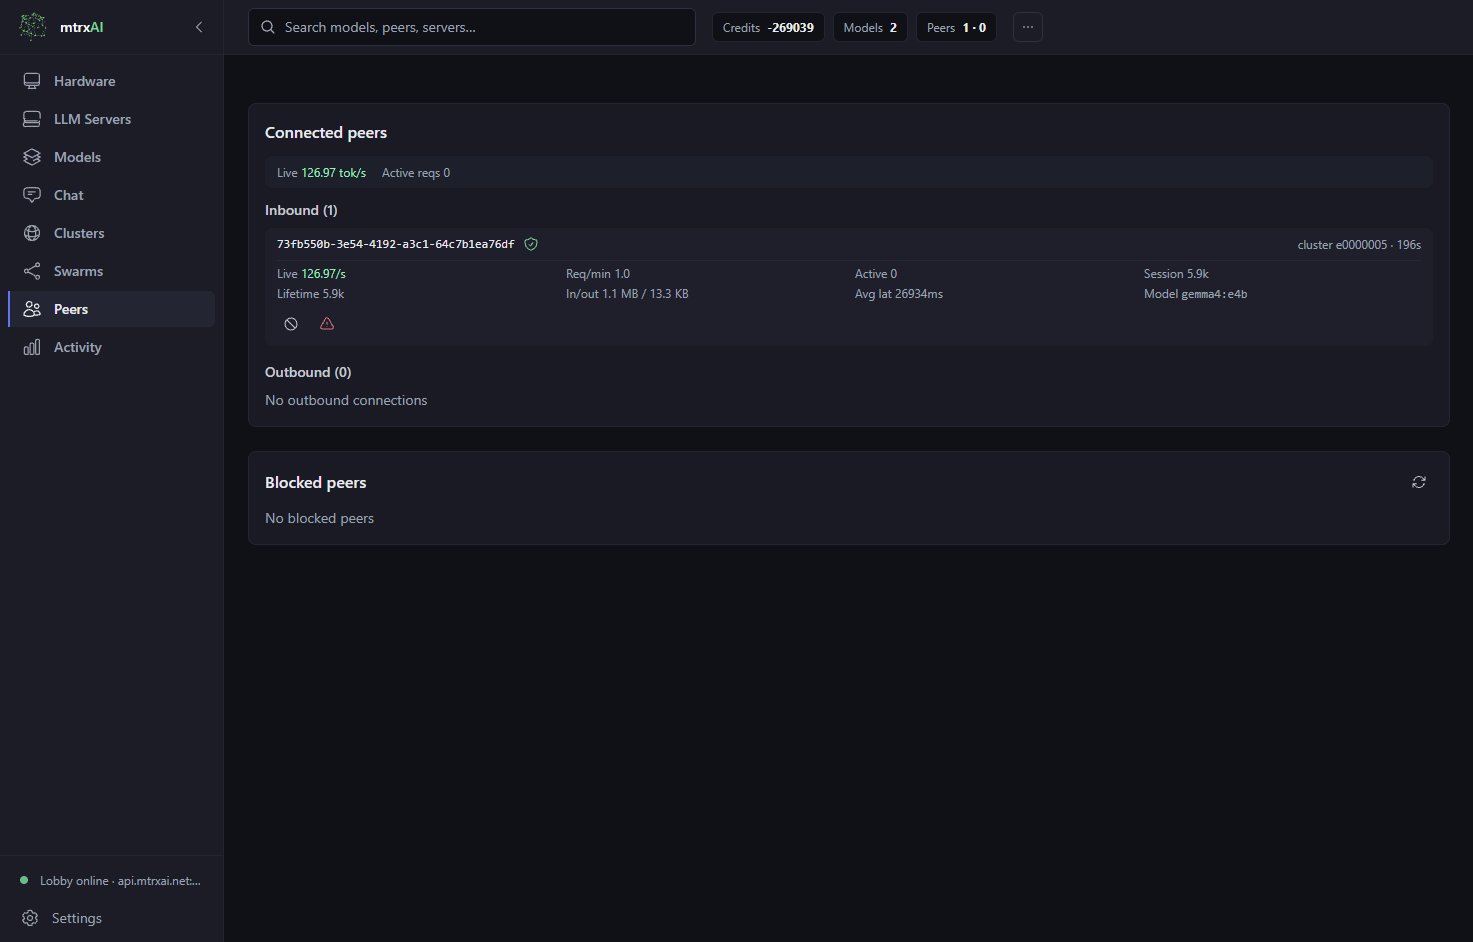
Approve who connects, block bad actors, and report abuse for operator review.
Activity & credits
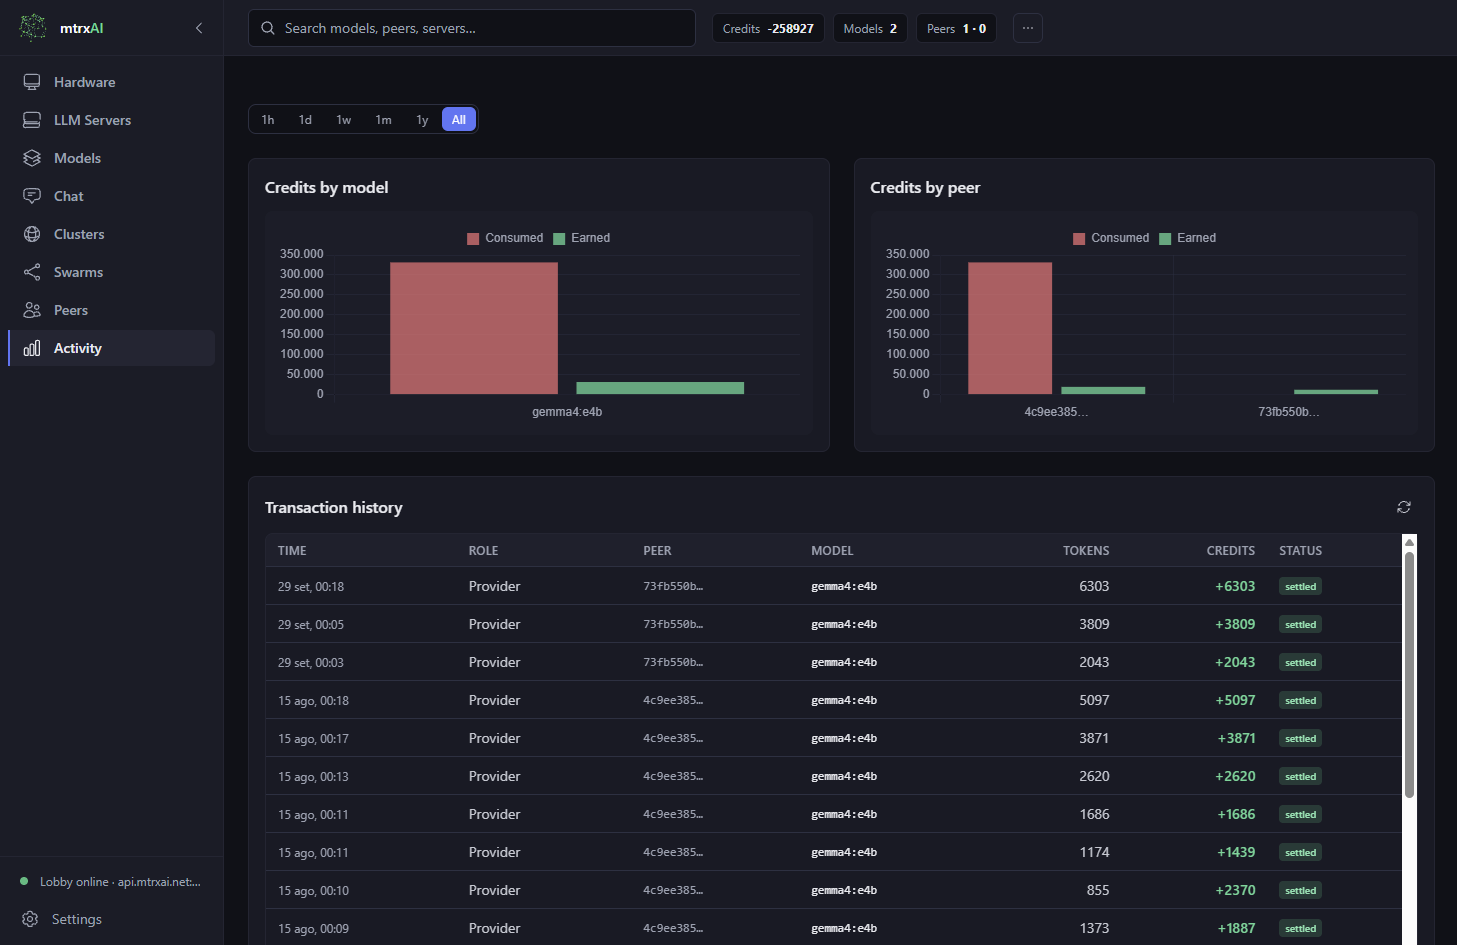
See usage history. Credits settle when both sides agree. Beta tokens have no monetary value.
Manage models & hardware
Unified LLM servers
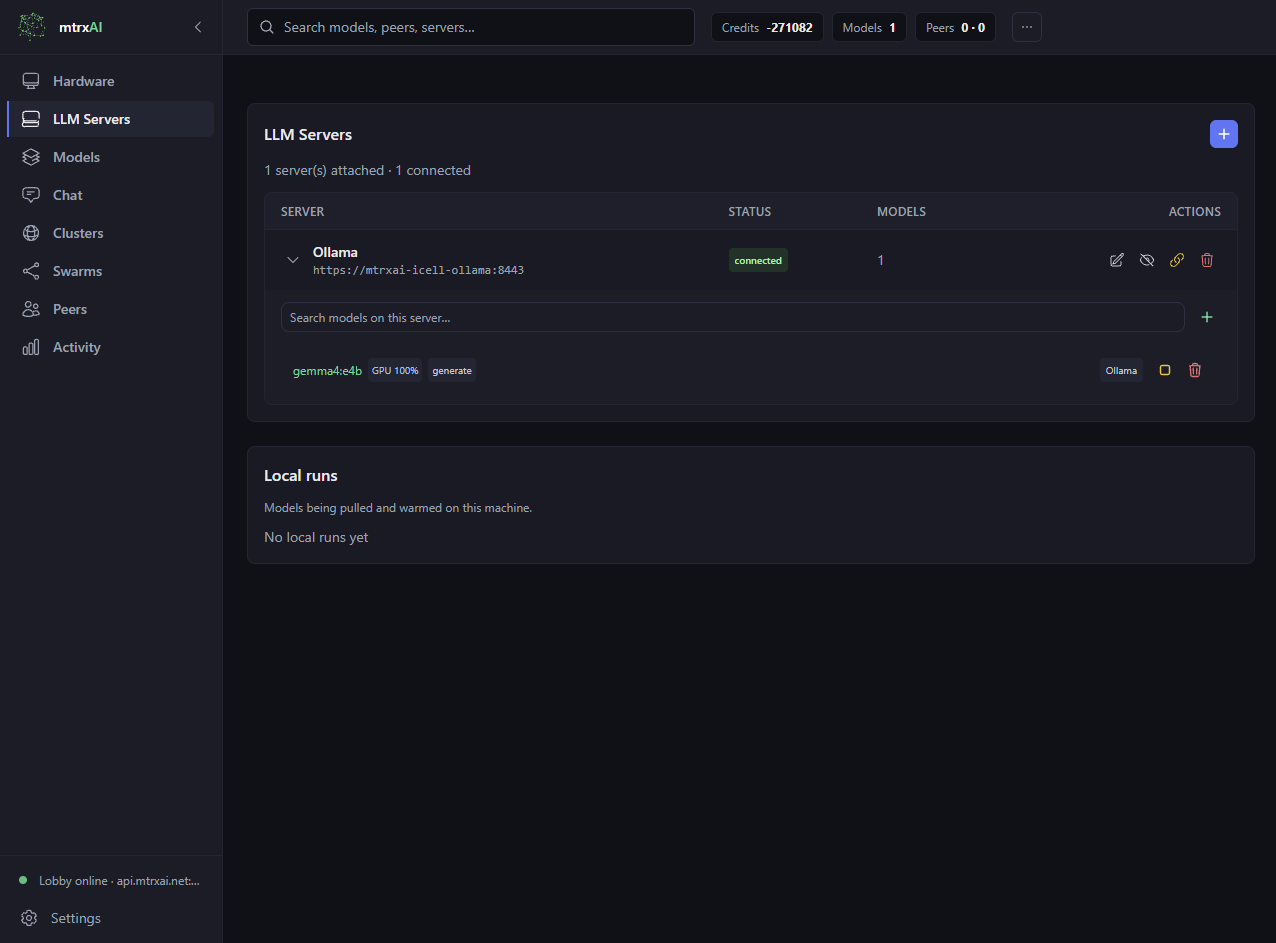
Attach and manage your local engines from one dashboard — scan, attach, detach, and health-check every backend in a single place.
Run new models
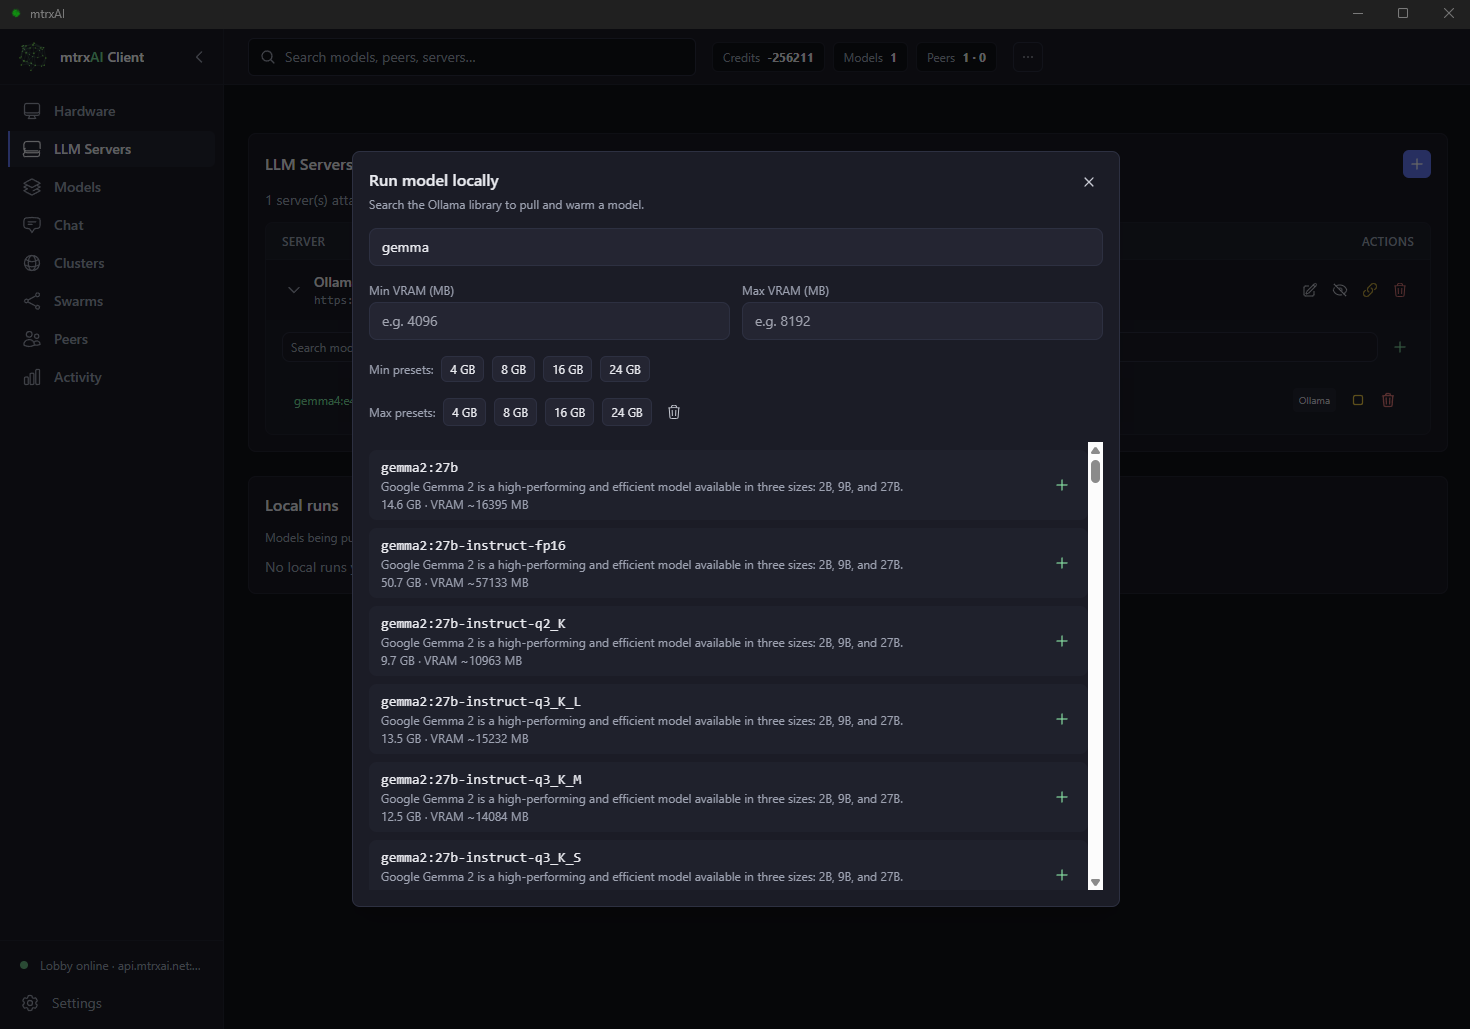
Pull and load models from your engines or a Hugging Face catalog. Wake an idle model on a peer with enough VRAM when you need it remotely.
Per-model visibility
Choose which models are shared with your cluster or swarm. Keep some local-only; expose others to teammates without opening the whole machine.
Resource controls
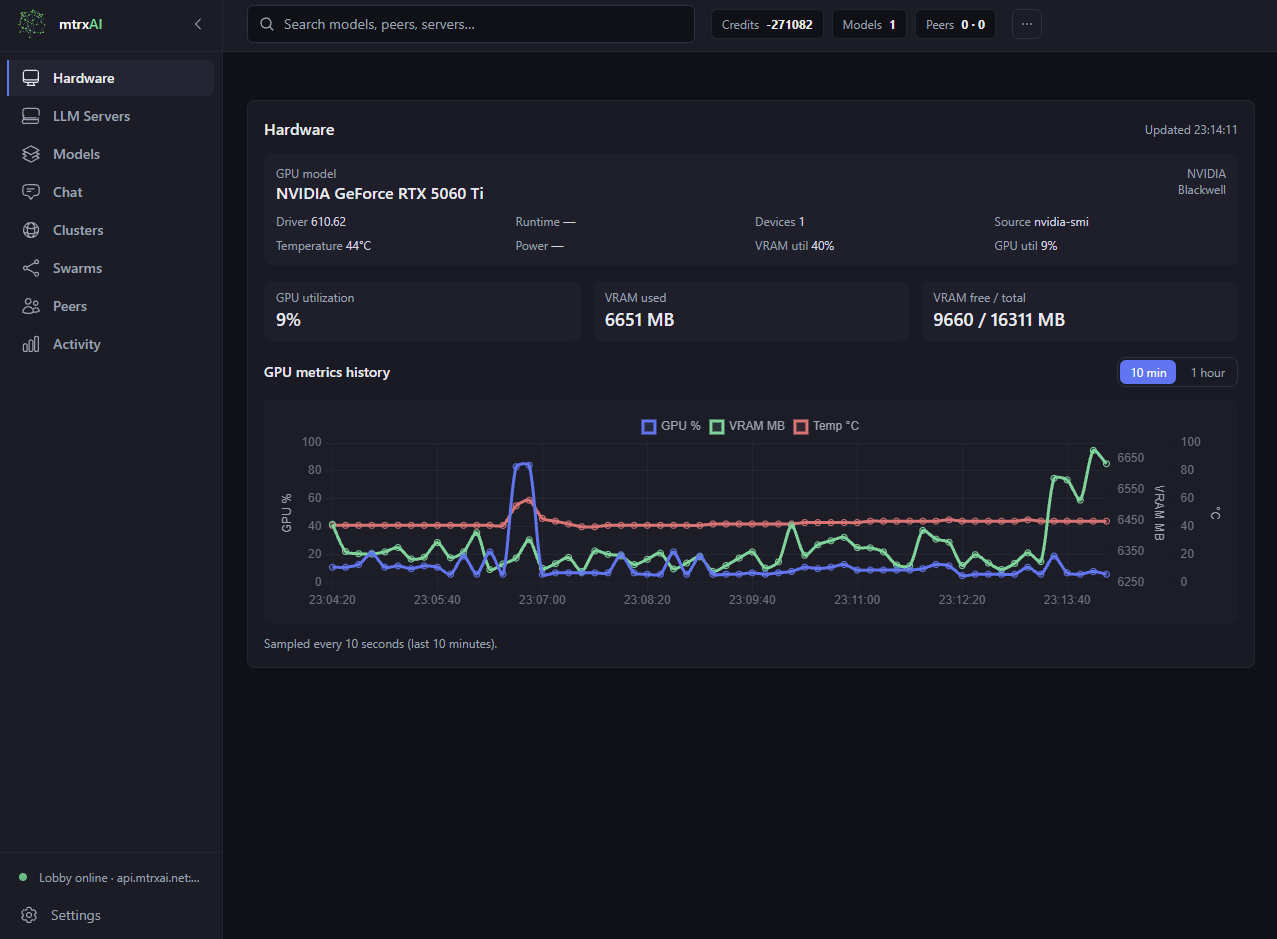
Sharing schedules, GPU thermal pause, and disconnect/pause for the whole node when you need the hardware back.
For API details, see For developers. For private and public teams, see Clusters.
Inside the dashboard
Hardware, servers, chat, peers, activity, and model pulls — click any screenshot to expand.
Getting started
Deploy
Pull mtrxAI from Docker Hub and register your device in the dashboard.
Join a network
Create or join a private team, a public regional cluster, or a small group with a shared token.
Attach engines
Connect your local model engines. mtrxAI merges them into one catalog for your apps.
Point your apps
Redirect AI tools to the local proxy. Sharing hardware is optional — approve each request or stay isolated.
Who it’s for
Engineers & agent builders
One local gateway for your stack. Use teammates’ models without copying multi-gigabyte weights.
Creators & designers
Offload heavy inference to a peer when local hardware is tight, then switch back instantly.
Hardware enthusiasts
Share idle GPU time and earn credits for when you need external compute.
Enterprise teams
Isolated private clusters — internal models hidden from public discovery.
Clusters
Join a private invite-only team or a public regional mesh. Models stay on the machines that load them; your apps keep talking to localhost.
Private and public
Private clusters
Invite-only. Join with name, ID, and password from the dashboard. Models and membership stay invisible to the public mesh — ideal for teams and offices.
Public clusters
Regional communities listed by the lobby. Anyone approved on the network can join to borrow or share compute with a wider set of peers — treat membership accordingly.
Both types use the same routing: local first, then a peer in that cluster. Credits and ranking apply on the cluster path. You can belong to more than one cluster at once, and run swarms alongside them.
How peers connect
Install mtrxAI on each machine, join the same cluster, and point your applications at the local proxy. When a model isn’t local, mtrxAI routes the request to a peer in that cluster.
mtrxAI helps the two computers find each other. Once connected, prompts and replies travel directly between them. If a direct path cannot be opened, mtrxAI can relay the connection.
Laptop + workstation
Develop on a light laptop while heavy models run on a rig with enough VRAM. Your IDE still targets the local proxy.
Office team
Link several workstations in a private cluster. Shared models stay off the public list; nearby peers are preferred automatically.
Regional public mesh
Join a public regional cluster to reach more peers when your private team is offline or short on VRAM.
Create or join
Create or pick a cluster
On a GPU machine, create a private cluster — or browse and join a public regional one from the dashboard.
Join from other machines
For private clusters, copy the invite details (name, ID, password). For public ones, select the region and connect. Each machine gets its own identity.
Share models on your terms
Attach engines, set per-model visibility, and connect. Remote models from that cluster appear in your local catalog.
Private invites: you will copy cluster name, ID, and password — enough for teammates to join the same team.
For how discovery and transport work under the hood, see Architecture.
Security & Privacy
You control visibility, sharing, and who connects. Inference travels peer-to-peer with transport encryption and application-layer end-to-end encryption enabled by default.
Controls that matter
Who can see you
Outsiders cannot discover your node unless they are in the same cluster or swarm. Private clusters stay invite-only.
What you share
Choose which models to expose, approve incoming requests, set sharing schedules, or pause and disconnect the whole node anytime.
Peer moderation
Block misbehaving peers locally and submit signed behavior logs for operator review.
Kill switch
Disconnect or pause all network links instantly when you need your machine back.
End-to-end encryption
Prompts and completions are encrypted between peers. The lobby helps with discovery and signaling — it is not on the inference data path.
Application-layer E2EE
Enabled by default (MTRXAI_E2EE_ENABLED). Proxy requests and responses use ChaCha20-Poly1305 AEAD after an ephemeral X25519 ECDH session. Plaintext proxy protocol v1 is rejected when E2EE is on.
Room & session keys
A room root key is derived from the cluster or swarm secret. Per request, peers negotiate an ephemeral session key (HKDF) so payloads are not readable by relays or the lobby.
Cluster path (WebRTC)
Transport uses DTLS on the data channel. On top of that, encrypted proxy frames (EncryptedProxyRequest / response) carry the inference payload when E2EE is enabled.
Swarm path (libp2p)
Transport uses Noise. Proxy protocol v2 adds the same ChaCha20-Poly1305 E2EE layer, plus HMAC-based ProxyAuthProof membership checks (replay window ~300s).
Transport & identity
Transport encryption
Cluster links: WebRTC DTLS/SRTP. Swarm links: libp2p Noise over TCP. Wire encryption protects bytes in transit; app E2EE keeps prompts opaque to anyone who is not a session endpoint.
Device attestation
Each machine carries an Ed25519 device key. The lobby can require attested client builds via challenge-response before registration.
Inference cell
Optional sealed icell runs the model engine beside the peer. Attestation can cover the cell so teams verify more than just the peer binary.
Lobby boundary
Lobby WebSocket carries discovery, SDP/ICE signaling, and credit reports — not prompts or completions. Short-lived TURN credentials may be minted for NAT relay; prefer TLS (wss://) to the lobby in production.
Local surface & settlement
Local proxy bind
The OpenAI-compatible proxy defaults to 127.0.0.1. Optional bearer token (MTRXAI_PROXY_TOKEN) can lock down local LLM routes.
Dual-verified credits
On clusters, credits settle only when consumer and provider report matching usage. Mismatches reject the transaction. Beta tokens have no monetary value.
Local secrets
Room keys, API keys, and transaction history live in the peer’s local encrypted store — not in the lobby catalog.
Confidential GPU (advanced)
On supported hardware, providers can advertise TEE / confidential computing trust levels. Consumers can prefer or require attested GPU environments. Optional inference sidecar keeps the P2P relay blind to plaintext.
Beta notice: Do not route regulated or highly confidential data through public clusters. Membership on a public cluster is weaker than a password-protected private cluster — treat public peers accordingly. See Terms & Privacy.
Architecture
How discovery, transport, and settlement work under the hood. For a plain-language path, start with How it works.
Lifecycle of a request
- Request dispatchedYour app sends an OpenAI-compatible API call to the local mtrxAI proxy.
- Local checkIf the model runs on your GPU, inference completes locally with no network delay.
- Peer discoveryIf the model isn’t local, mtrxAI queries your cluster or swarm for peers running it.
- Provider selectionCandidates are ranked by network proximity, geography, and load.
- Direct tunnelPeers open a data channel. The lobby relays connection setup only — prompts and responses travel peer-to-peer. If hole punching fails, short-lived TURN credentials from the lobby enable relay.
- Credit settlementOn clusters, both machines sign off on token usage; the ledger updates. Swarms have no central ledger.
Clusters vs swarms
Mix topologies concurrently — regional clusters for discovery and credits, swarms for small trust circles.
| Managed clusters | Decentralized swarms | |
|---|---|---|
| Primary use | Teams and regional communities with discovery, ranking, and credit tracking. | Small high-trust groups with minimal central coordination. |
| Joining | Public regional index or private cluster (name + UUID + password). | Shared cryptographic Swarm token. |
| Economics | Transparent credit accounting between peers. | Honor system — no ledger. |
| Transport | Lobby signaling, then direct WebRTC data channels (DTLS). TURN relay when needed. | libp2p gossip — decentralized coordination with application-layer E2EE. |
| Network setup | No inbound ports; STUN/ICE hole punching, TURN fallback. | libp2p hole punching with optional relay fallback. |
Lobby role
Discovery & signaling
The lobby helps peers find each other and exchange connection metadata. It does not carry inference payloads.
Credits (clusters only)
Usage reports reconcile on the lobby ledger when both peers agree.
ICE / TURN
The lobby can mint short-lived TURN credentials so WebRTC sessions succeed behind restrictive NAT.
For Developers
One OpenAI-compatible API on localhost. Attach the engines you already run; mtrxAI routes to local hardware or the mesh.
OpenAI-compatible API
Drop-in endpoint
Point tools at the local proxy (default localhost:11345). Use standard /v1/chat/completions and related routes.
Streaming & tools
Streaming responses, tool calling, and structured JSON work with agent stacks that speak OpenAI Chat Completions.
Unified catalog
Local models and mesh models appear in one list. Local-first routing; remote only when needed.
Attach your engines
mtrxAI talks to backends — it does not replace them. Connect what you already use:
- Inference cell — sealed model engine shipped with peer deploy stacks
- vLLM, llama.cpp, LM Studio — OpenAI-compatible HTTP servers
- Ollama — attach as a local engine when you already run it
- Hosted APIs — optional custom / OpenAI-style remote endpoints
Apps always see the OpenAI-compatible surface on the peer. Engine choice is configuration, not a second public API.
Ready to integrate?
Pull the Docker image, open the dashboard, and point your client at the local proxy base URL.
Docker Hub